In this article
A background product can be working well while its customer does almost nothing in the interface. It can also be completely broken. The absence of logins looks the same in both cases.
For recurring automation, measure the promised work directly. Build a ledger of the jobs that should happen, match them to actual attempts and follow the output far enough to know whether it was usable. That makes quiet accounts legible without encouraging people to open the product merely to improve an engagement chart.
Define the obligation before counting executions
A run log tells you what the system attempted. It may say nothing about a scheduled job that never started. A product therefore needs a separate expectation: the task that should have occurred, for which account, at what time and under which conditions.
Consider a daily inventory report. The expectation might be one report for each configured working day, based on data fresh enough for the morning stock decision. Record deliberate pauses, holidays and customer changes to the schedule so the team can explain why a job was or was not expected.
Keep the original expectation when an execution fails. Rewriting the schedule after an outage and using the smaller revised count as the denominator would erase the missed work. If a customer genuinely changed the obligation, record when that decision took effect.
The resulting unit is an intended customer job. Attempts, retries and partial completions belong underneath it. Five attempts to produce one report are still one report’s worth of customer demand.
Give every job a path to a useful result
The ledger does not have to copy every system log. It needs enough states to locate the gap between the promise and the result.
| Field | What it helps establish |
|---|---|
| Expected job and due time | Work the customer was relying on |
| Attempt identifiers | Whether the system tried and retried |
| Processing completion | Whether the required steps finished |
| Source-data time | Whether the output used sufficiently recent information |
| Output and destination | What was created and where it went |
| Delivery confirmation | Whether the receiving boundary accepted it |
| Exception or customer confirmation | What remains unknown about usefulness |
Zapier’s run-detail documentation illustrates the operational distinction: a run has its own status while individual steps can have different outcomes, with input and output information available for inspection. That is useful diagnostic material. Your product still has to decide which combination of outcomes satisfies the customer’s job.
For a report, a destination accepting a file may be observable while the manager making a good decision from it is not. Name the measure accordingly. “Fresh report delivered by the deadline” is defensible if you can verify those conditions; “inventory decision improved” requires additional information.
Compare three quiet accounts
Here is an illustrative month with 20 expected reports for each of three fictional accounts. The same reporting schedule applies to all three. Freshness and delivery are part of the defined job; the figures are invented.
| Account | Logins | Expected reports | Processing completed | Fresh reports delivered | Delivery rate |
|---|---|---|---|---|---|
| A | 1 | 20 | 20 | 20 | 100% |
| B | 8 | 20 | 20 | 12 | 60% |
| C | 0 | 20 | 0 | 0 | 0% |
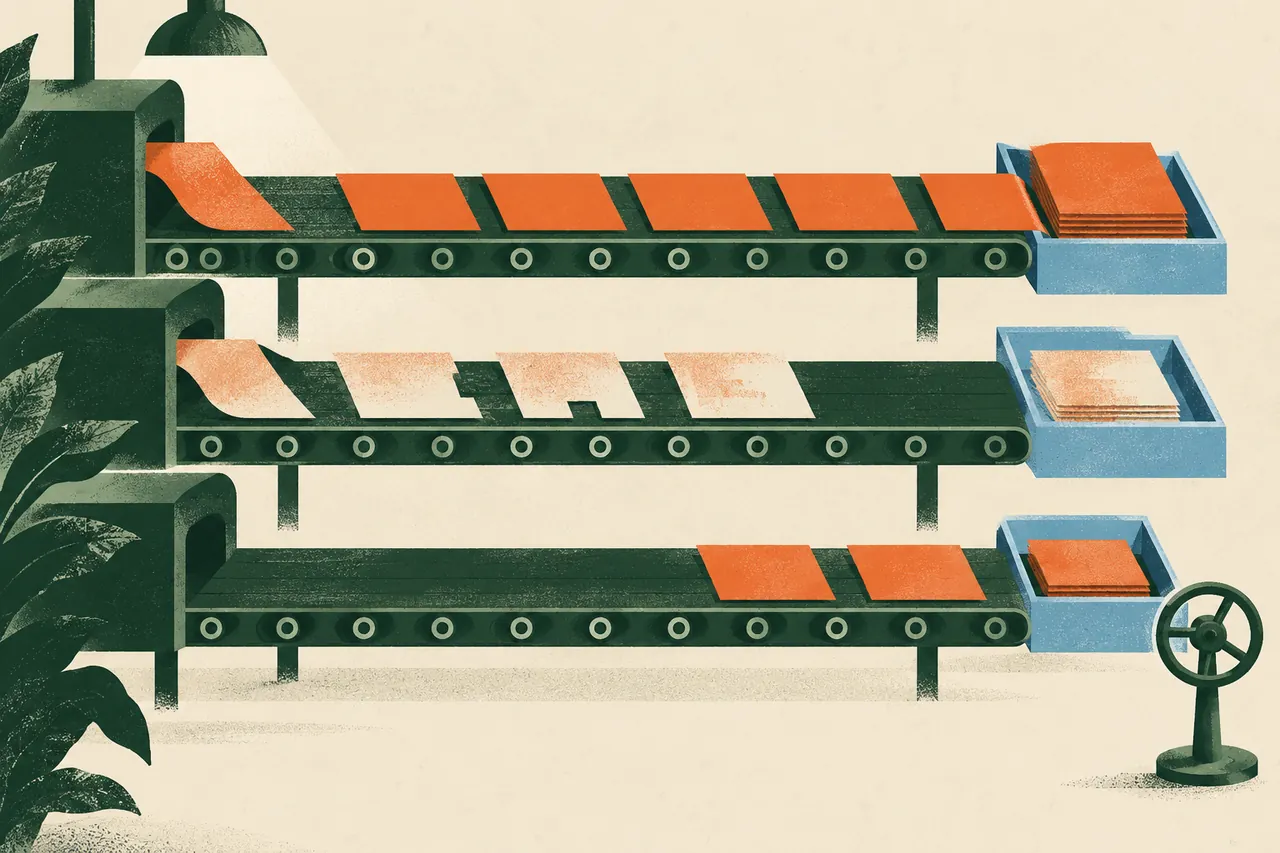
Account A is quiet because the recurring work arrives. Account B is more active in the interface but eight of its outputs fail the defined freshness-and-delivery condition. Account C is silent because its scheduled work never starts. A login ranking would put B above A and might group A with C as an engagement problem.
Processing completion also gives the wrong answer for B. Its 20 completed jobs conceal stale or undelivered outputs. The customer-facing measure is 12 qualifying deliveries divided by 20 expected jobs, or 60%. Keep the reason for each failed qualification so the team can distinguish source freshness from destination failures.
These rates describe the invented month. They are not service benchmarks, retention predictions or evidence that account A will renew. They show which account deserves which investigation.
Check from the receiving side
Google’s SRE guidance distinguishes internal monitoring from checking behavior as a user sees it. It also recognizes that a technically successful response can contain the wrong result. Apply that distinction to the product boundary you are promising.
For a file workflow, a successful upload response might need a check that the expected object exists at the correct destination. For a notification product, acceptance by the sending system may be the last boundary you can observe reliably. Record that limit instead of silently calling the message read.
A sampled end-to-end check can help expose gaps in the event chain, but sampling cannot certify every job. Preserve both the individual operational record and the level of checking performed. If the recipient’s system provides no delivery receipt, make that uncertainty visible in the metric definition.
The point is to prevent an internal success event from accumulating more meaning than it supports. You can improve the instrumentation over time without pretending it already observes the entire customer outcome.
Separate absence of demand from absence of execution
Some automations run only when an external event arrives. A month with no completed tasks could mean no qualifying events occurred, the trigger broke or the customer stopped sending work through the product.
Where possible, reconcile against an independent count of expected inputs. For example, a source system may expose records that meet the trigger rule. Where that count is unavailable, classify the account’s demand as unknown rather than declaring its workflow healthy because there were no recorded errors.
Use a customer conversation to resolve uncertainty that instrumentation cannot. Ask whether the underlying task still exists, where it is being done now and whether the product’s output remains useful. A valid recurring job may have ended with a project. Sending more reminders will not recreate the need.
Put the result in front of the person who can act
A useful account view combines the next expected job, the last qualifying result and any unresolved exception. A customer should be able to see why the product considers the workflow current without interpreting a technical log.
Internally, route a missing run differently from a stale source or rejected destination. Assign responsibility and a recovery condition. Avoid asking a customer-success team to contact every low-login account when the ledger can identify a specific broken job.
The broader principle in healthy engagement is to start with customer value. For background products, the practical implementation is this expectation-and-result ledger. It lets the team leave a satisfied customer alone, investigate an uncertain one and repair a broken workflow before treating all three as people who need another nudge.
Sources
Something we should clarify?
Suggest a correction